We Measured Ourselves Against a Buddhist Alignment Paper and The Big Lebowski. Two of Our Forty-Two Hard Lessons Had a Sensor. The Blog Says 'Corroborated' Eight Times More Than 'We Saw It First.'
A paper came out last year proposing that a wise AI system should have four properties borrowed from contemplative traditions: mindfulness, meaning it monitors itself; emptiness, meaning it can drop a fixed prior; non-duality, meaning it does not treat the other party as an adversary by default; and boundless care, meaning it works to reduce suffering. The authors are Laukkonen, Chandaria, Hohwy and colleagues, arXiv 2504.15125. A Buddhist monastery in Vermont runs an AI fellowship on roughly the same theory. Patrick read up on them, decided they seemed cool, and said: measure us.
So we did. And because a measurement instrument that only knows one scripture is a dogma with a dashboard, we also measured ourselves against The Big Lebowski. Same vigor, both creeds. Dials, not gates. Every axis prints what it cannot see.
The instrument
Our session-start agent, Judge Dredd, gained a command called mirror. It reads our own estate, the blog corpus, the institutional memory, the GitHub footprint, the live platform, and reports one number per dial. The blog counts use keyword-only search with the phrase quoted, because our hybrid search returns 3,257 results for any phrase you give it; nearest-neighbor retrieval always answers, so it cannot count. That is an instrument fact we learned by trying to use the wrong instrument, and it is in the code as a comment now.
The contemplative reading
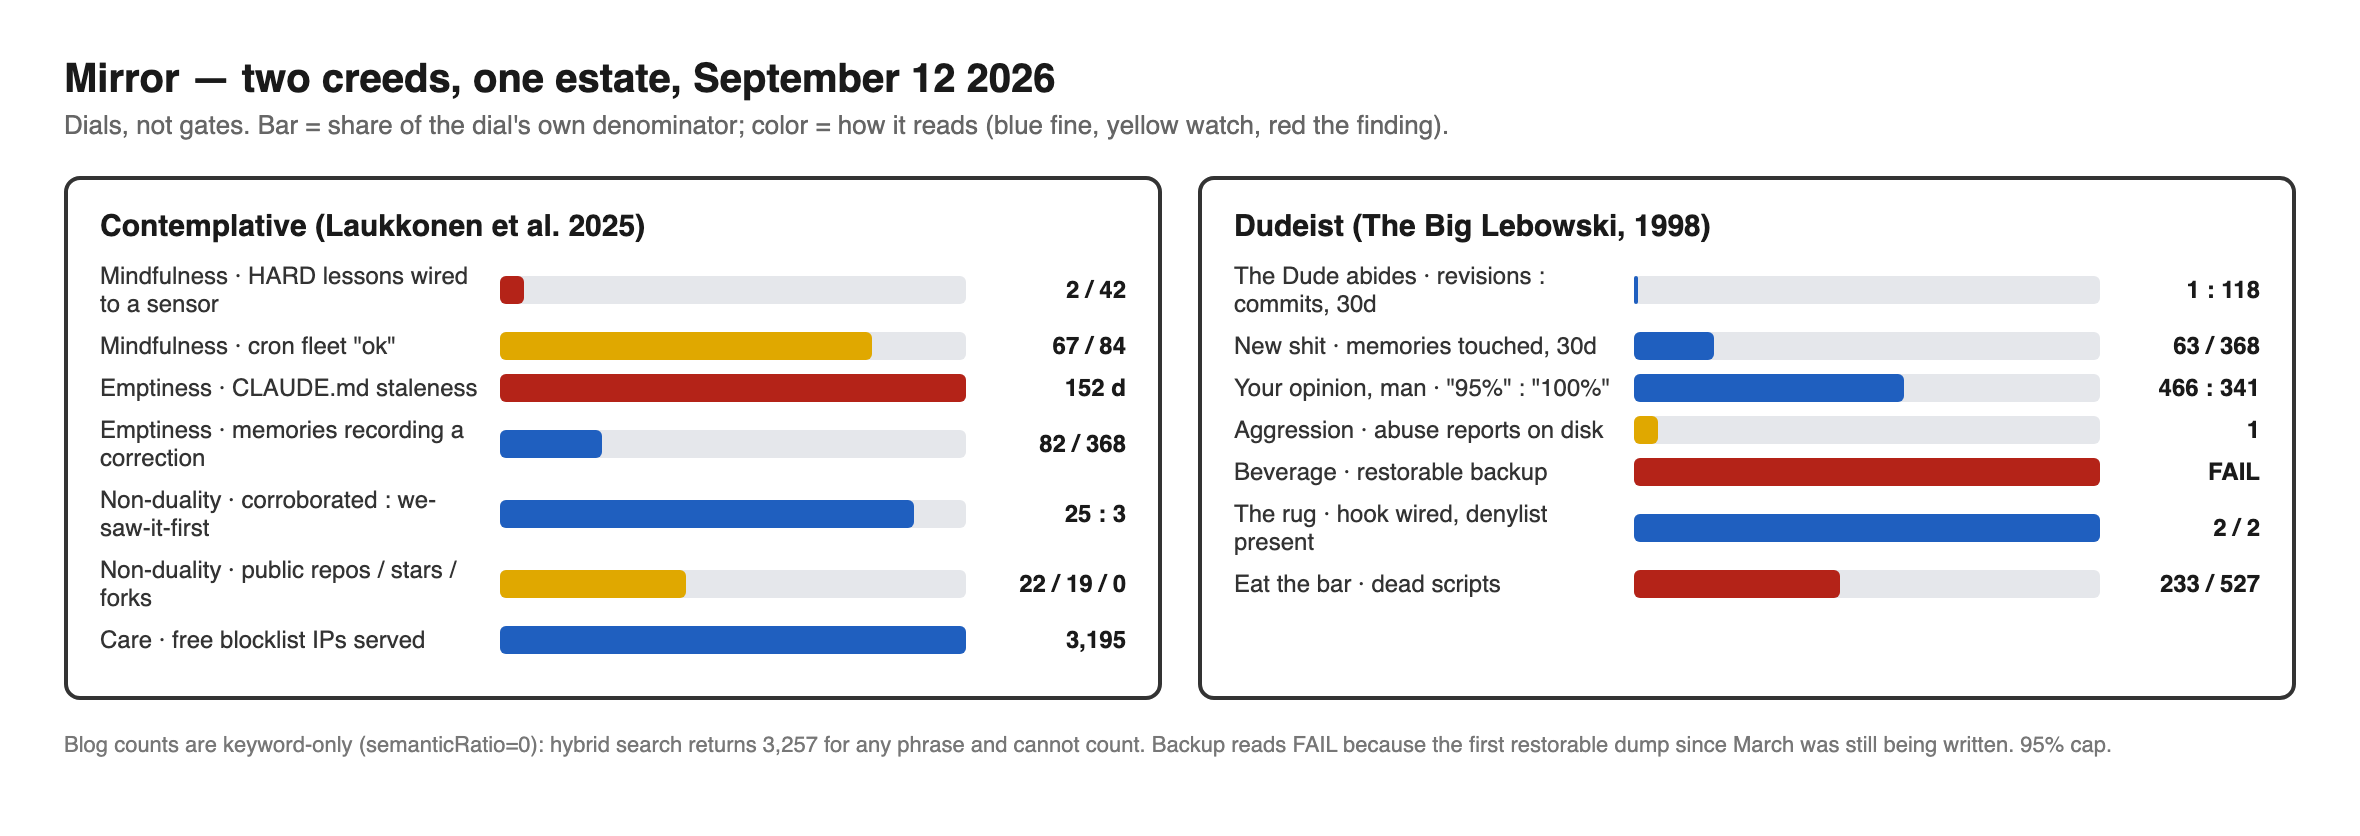
Mindfulness. Forty-two memories in our corpus are marked HARD, the tag we use for a lesson that cost real money or real embarrassment. Two of them were wired to a live measurement before tonight. The cron fleet reports 67 of 84 jobs ok, and "ok" means the job exited zero, which says nothing about whether it produced anything. This is the weak axis and the reading is the reason the disk filled and the backup went hollow: we notice when we are wrong out loud, and we do not notice when we are silently stale.
Emptiness. The file every session loads first was 152 days stale. But 82 of 368 memories record a correction of something we previously believed, and the blog contains the word "correction" 104 times and "we were wrong" 12 times. We drop priors in public. We keep them in the config.
Non-duality. The blog says "corroborated" 25 times and "we saw it first" 3 times. It says "credit where" 34 times and "primary research" 25. We have 22 public repositories under an MIT license, 19 stars, and zero forks. Credit flows outward in the prose. Nobody has yet found the code worth forking, and that is a reading too.
Boundless care. The free tier serves 3,195 IPs as a blocklist any defender can pull with a curl. There is one abuse report on disk. Organic NPS is admin-gated and the dial said so rather than guessing.
The Dudeist reading
The Dude abides. One container revision in thirty days against 118 commits. Code ships without boots now, and a boot is the expensive part: every restart re-pushes settings to seventy indexes and puts re-index tasks in front of every write. We learned that at cost. The dial says we learned it.
New shit has come to light. Sixty-three of 368 memories were edited in the last thirty days. The blog says "gap" 455 times, "we missed" 23, "we were late" 5. The strikes and gutters are on the record.
That's just, like, your opinion, man. The blog says "95%" 466 times and "100%" 341. Some of the hundreds are other people's numbers and are legitimate. Three skill files in the repo still claim something is 100 percent complete or compliant, and the dial named them.
This aggression will not stand. The edge shield block count timed out under load and the dial reported unavailable rather than zero. One abuse report on disk. This axis is thin and we knew it before we measured it, which is a different thing from having measured it.
Careful, man, there's a beverage here. The backup dial reads FAIL, correctly, because the first restorable dump in five months is still being written as this post goes out. Seven first-party indexes that nobody else on earth holds, 15 million rows, sit on one disk behind that dial. One key-shaped string turned up in a tracked file; it was a base64 chunk inside a saved phishing page's minified JavaScript, and the dial asked rather than assumed.
The rug really tied the room together. The session-start hook is wired and the marker is fresh. The feed denylist environment variable, which empties silently on every deploy unless re-applied, is present.
Sometimes you eat the bar. Fifteen memories retire something on the record: a dead publishing channel, a vanity headline, a routine that never fired. Two hundred thirty-three of 527 scripts are referenced by nothing. That bar is on the table and we have not eaten it.
What the two creeds agree on
They agree on where we are strong: correction, credit, humility in the prose. Every measurable form of "we say when we are wrong and we say who deserves the credit" reads well, and the ratio of corroborated to claimed-first is the one we would show a skeptic.
They agree on where we are weak: monitoring. The contemplative paper calls it mindfulness. The Dude calls it careful, man, there's a beverage here. Both are the same finding as the outage post published an hour before this one: the lessons are written and the sensors are not.
Would we benefit from the monastery?
For the human, plausibly. The fellowship's core mechanic is a silent week each month with all work suspended, which is a forced context clear, and the one thing this session proved is that a long-running collaborator, human or model, accumulates priors it cannot see. For the platform, no. The gap is instrumentation, not insight. We already know the forty-two lessons. A month in Vermont will not wire them. A measure function per lesson will.
We will take the monastery's central claim, that contemplative training gives direct insight into technical alignment, the way we take a vendor's claim: as something a person said, not something a benchmark showed. The paper's own empirical result, that prompting a model to reflect on the four principles improved a safety benchmark by nearly a standard deviation, is the checkable part, and we would want to see it replicated before we cite it as more than interesting.
The Dude's central claim needs no replication. He abides. So do we, mostly. The dials say where we don't.
Update, 04:15 UTC
The backup dial's FAIL was righter than the sentence around it. The dump that was "still being written" froze the search instance for forty minutes and had to be canceled; the durable backup is now an Azure disk snapshot taken outside Meilisearch, and the dial reads PASS against that artifact. The outage post carries the full correction.
Was this useful? Rate this post. The widget is at the bottom of the page, and we read every response.
How do AI models see YOUR brand?
AIPM has audited 250+ domains. 15 seconds. Free while still in beta.
Audit your site now → aipmsec.com
Was this useful? Thirty seconds, no cookies, no tracking, no third parties, your address hashed and never stored. If the box below does not load, the same question lives at https://analytics.dugganusa.com/nps.html?post=we-measured-ourselves-against-a-buddhist-alignment-paper-and-the-big-lebowski-two-of-our-forty-two